Cut your coding agent's inference bill by up to 85%.
Point your agent at the endpoint and let Intelysis prune context, compress tool logs, and validate the answer. Your provider bill, minus the waste.
Measured on a coding suite
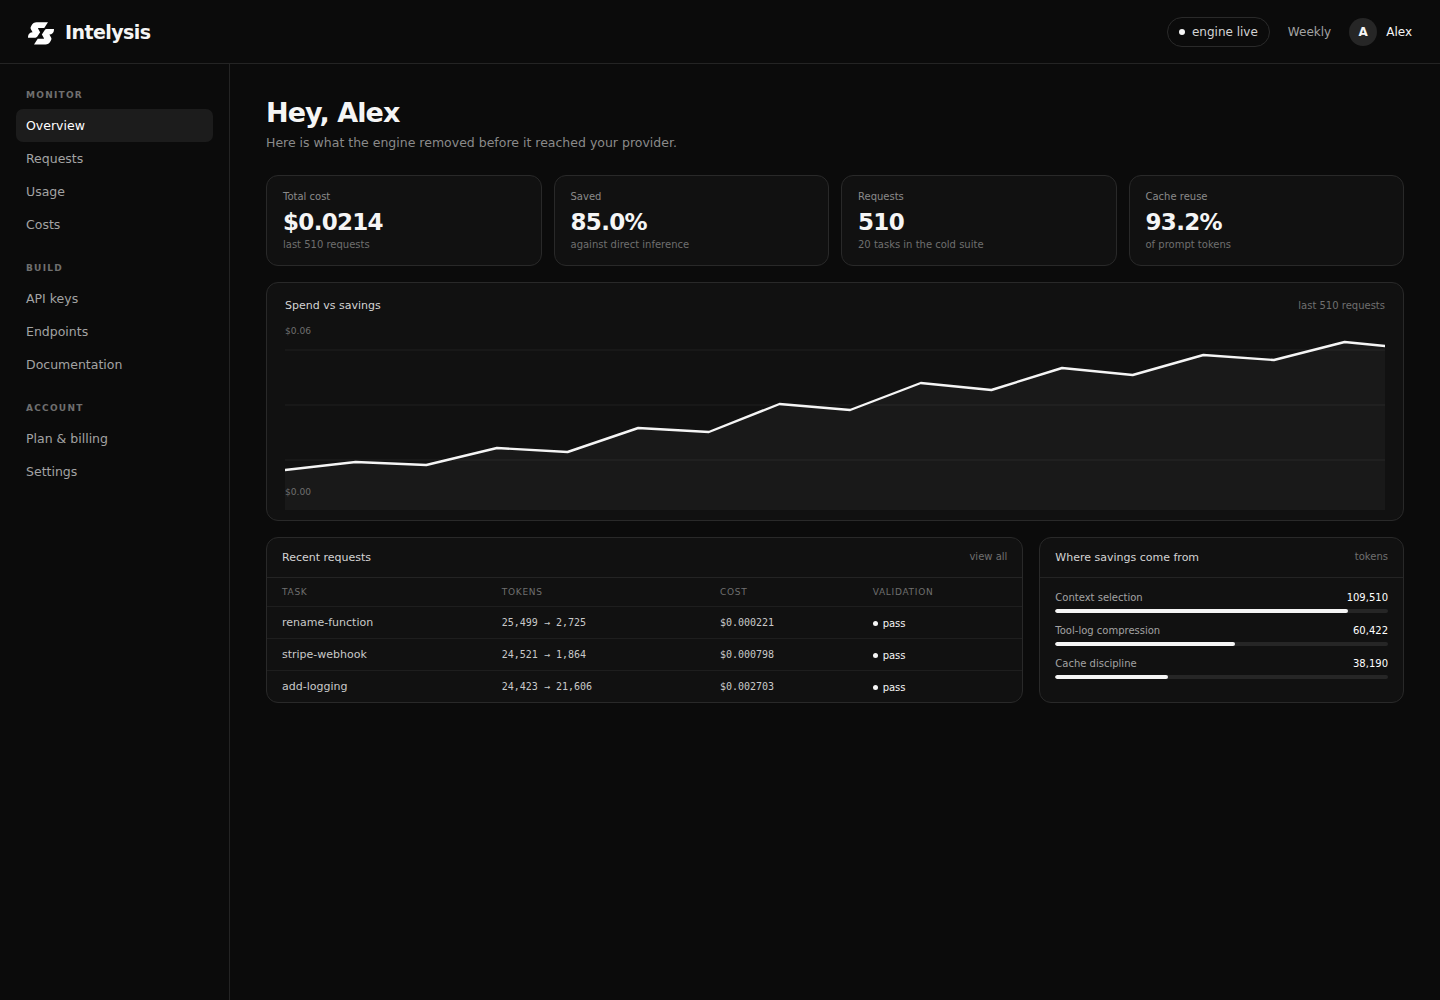
 Intelysisengine live
Here is what the engine removed before it reached your provider.
Everything you need to cut inference cost.
Intelysis reads the task, sends only the files it touches, compresses the newest tool log, keeps the cacheable prefix stable, and validates the answer before you pay for it.
See the reportRequest report
Fix the failing webhook test
Context selection
Only the files the task names, plus one hop of relative imports, reach the provider. Noise modules are dropped before inference.
Cache-aware repetition
Unchanged state is sent as a reference rather than resent, so repeated turns bill at the cache rate instead of the full input rate.
Output contracts
Every request declares its shape and is validated before you pay for it. A failed answer retries with the missing context.
Per-request report
Every response carries tokens before and after, cache hits, cost and latency. You audit the saving on your own traffic.
Key control, enforced
Your key is encrypted at rest, used only for your workspace, and never returned to the browser.
Built for the scale of coding agents.
Intelysis runs between your agent and your model provider on the same OpenAI wire format. No new SDK and no retry tax.
Repo-heavy tasks
The file tree is pruned to the files the task names, plus one hop of relative imports.
Tool-heavy tasks
The newest tool result keeps its head, tail and every error, path and stack line.
Repeated turns
The cacheable prefix stays byte-stable, so repeated context keeps its cache hit.
Low-saving tasks
Small prompts pass through unchanged because compressing them would cost more than it saves.
What the measured run shows.
Measured results, not testimonials. Coding suite from 2026-11-12, direct DeepSeek versus Intelysis.
Most coding tasks cut 89–97% of prompt tokens. The same answers passed in both arms.
webhook test
Cline · 92.4% lower bill
The rename task kept 2 files and dropped 60. 25,499 → 2,725 input tokens.
rename-function
OpenCode · 89.3% fewer tokens
The low-saving case still came out 11.5% cheaper: 24,423 → 21,606 tokens.
add-logging
measured coding suite · 0 retries
Your key is encrypted at rest, used only for the workspace, and never returned to the browser.
key handling
Key encrypted at rest
Every task returned the expected files and symbols, with zero retries. The optimizer did not buy savings by skipping work.
validation
measured coding suite · 0 retries
Cache hits stayed above 90% because the cacheable prefix is deterministic and byte-stable.
cache-discipline
measured coding suite · 93.2% cache reuse
Simple pricing. The same engine on every plan.
Bring your own model key and pay your provider directly. Intelysis charges a flat plan fee, never a markup on tokens.
Select preferred billing cycle
Budget
$98 per month,
billed monthlyannually
- Bring your own key
- 60 requests / minute
- 1 API key
- Request reports + savings
Pro
Most popular$1916 per month,
billed monthlyannually
- Bring your own key
- 300 requests / minute
- Up to 10 API keys
- Full analytics + email support
Scale
$39 / month,
billed monthlyannually
- Bring your own key
- 2,000 requests / minute
- Unlimited API keys
- Priority support + usage export
Usage
Rate limits and API keys
Select preferred
billing cycle
Frequently asked questions.
Quick answers about setup, the engine, and billing.
Setup
Engine
Billing





Connect your key and measure
the first request.
Bring your own model key. No card today; plan checkout is being enabled.
Connect your key